CallEnhancer, and the enterprise speech stack we are building on it
Our open source speech enhancement model cuts character error rate on a private call centre set from 71.48% to 19.01%. Here is what we are building on top of it.
We've always been committed to contributing to the open source community and making advanced speech AI more accessible. That commitment led us to release CallEnhancer, our open source speech enhancement model, for developers and researchers to explore, test, and build upon.
Building on that foundation, we are now developing an enterprise grade, end to end speech AI stack designed for production environments. It delivers stronger performance, greater robustness, and higher transcription accuracy across real world business applications.
From customer support and contact centres to enterprise voice AI, our goal is to build speech enhancement technology that performs reliably at scale while continuing to support and contribute to open source.
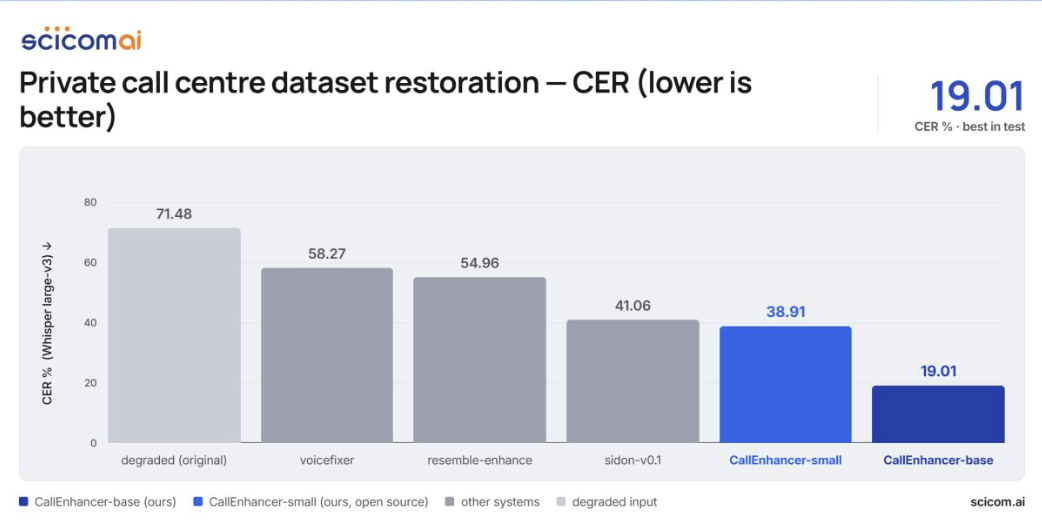
The comparison runs every system over the same held-out call centre audio and scores each one the same way. Raw 8 kHz telephony audio, left alone, reaches a character error rate of 71.48%. CallEnhancer-small, which is the open source release, brings that to 38.91%. CallEnhancer-base reaches 19.01%.
This work follows an earlier experiment in multilingual speech enhancement covering more than 150 languages, including Malaysian context switching, running at 200× real time on a single H100.
Explore CallEnhancer on Hugging Face: Scicom-intl/CallEnhancer.
First published on LinkedIn, 19 August 2026. The figures are reproduced as published; the test set is a customer corpus and is not redistributable.